Failed pipelines, broken golden records, and poor data quality don’t just slow teams down. They quietly sink AI programs before they ever get off the ground.
In this live session, Srinath Reddy B joins Chris Gambill to dig into what it really costs a business when data breaks.
Watch Now
They start with the operational reality of data governance and data engineering at enterprise scale. Then we look at why the modern data stack stopped working: tool sprawl, heavy operational overhead, and $180K senior engineers spending their weeks on manual maintenance instead of building value.
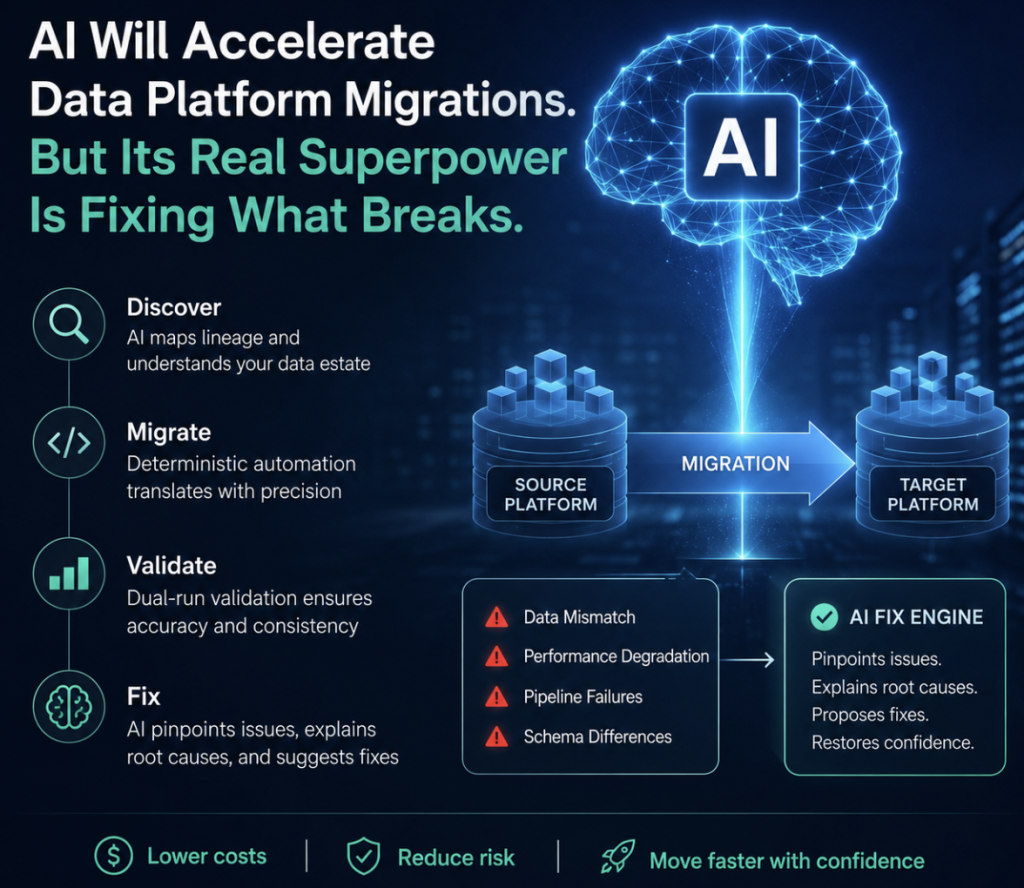
From there, Srinath walks through how BigHammer approaches the problem, and we skip the happy path on purpose. Discover how the platform handles failure, how it avoids cloud and vendor lock-in, and how its Domain Specific Language and Context Layer keep an AI agent from writing a bad SQL query or dropping a critical table.
Watch above as we cover:
- The real business cost of pipeline failures, bad data quality, and broken golden records
- Why tool sprawl and manual maintenance are wasting your payroll
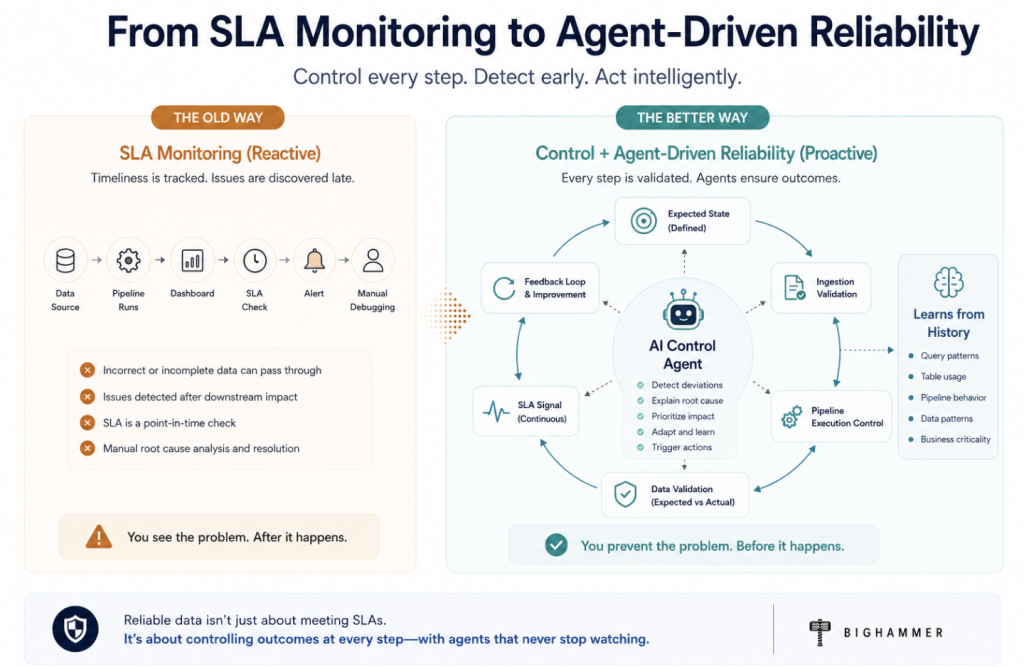
- Designing for failure instead of the happy path
- Avoiding cloud and vendor lock-in
- How guardrails and context layers keep AI agents from doing damage in production
- How AI and NLP are changing data engineering work
- Upskilling your team for an AI-driven future
They’ll also get into the claims behind lower total cost of ownership and a big cut in labour effort through NLP and no-code automation.
Discover what’s next. How is AI changing the day-to-day work of data engineers?
And how do data leaders upskill their teams and turn their departments from cost centers into revenue generators?
Many thanks for a great fireside chat to
Chris Gambill, Founder, Gambill Data (https://www.gambilldata.com)